Stop Chasing the Best AI Model. Start Measuring the Cost of Getting the Job Done.
OpenAI continues to evolve its models and Codex ecosystem. Anthropic is pushing Claude's reasoning and coding capabilities. xAI is competing with Grok. DeepSeek continues to put pressure on the economics of powerful models. Google is expanding Gemini and its agentic development ecosystem, while Meta is making another serious push with Muse Wonder.
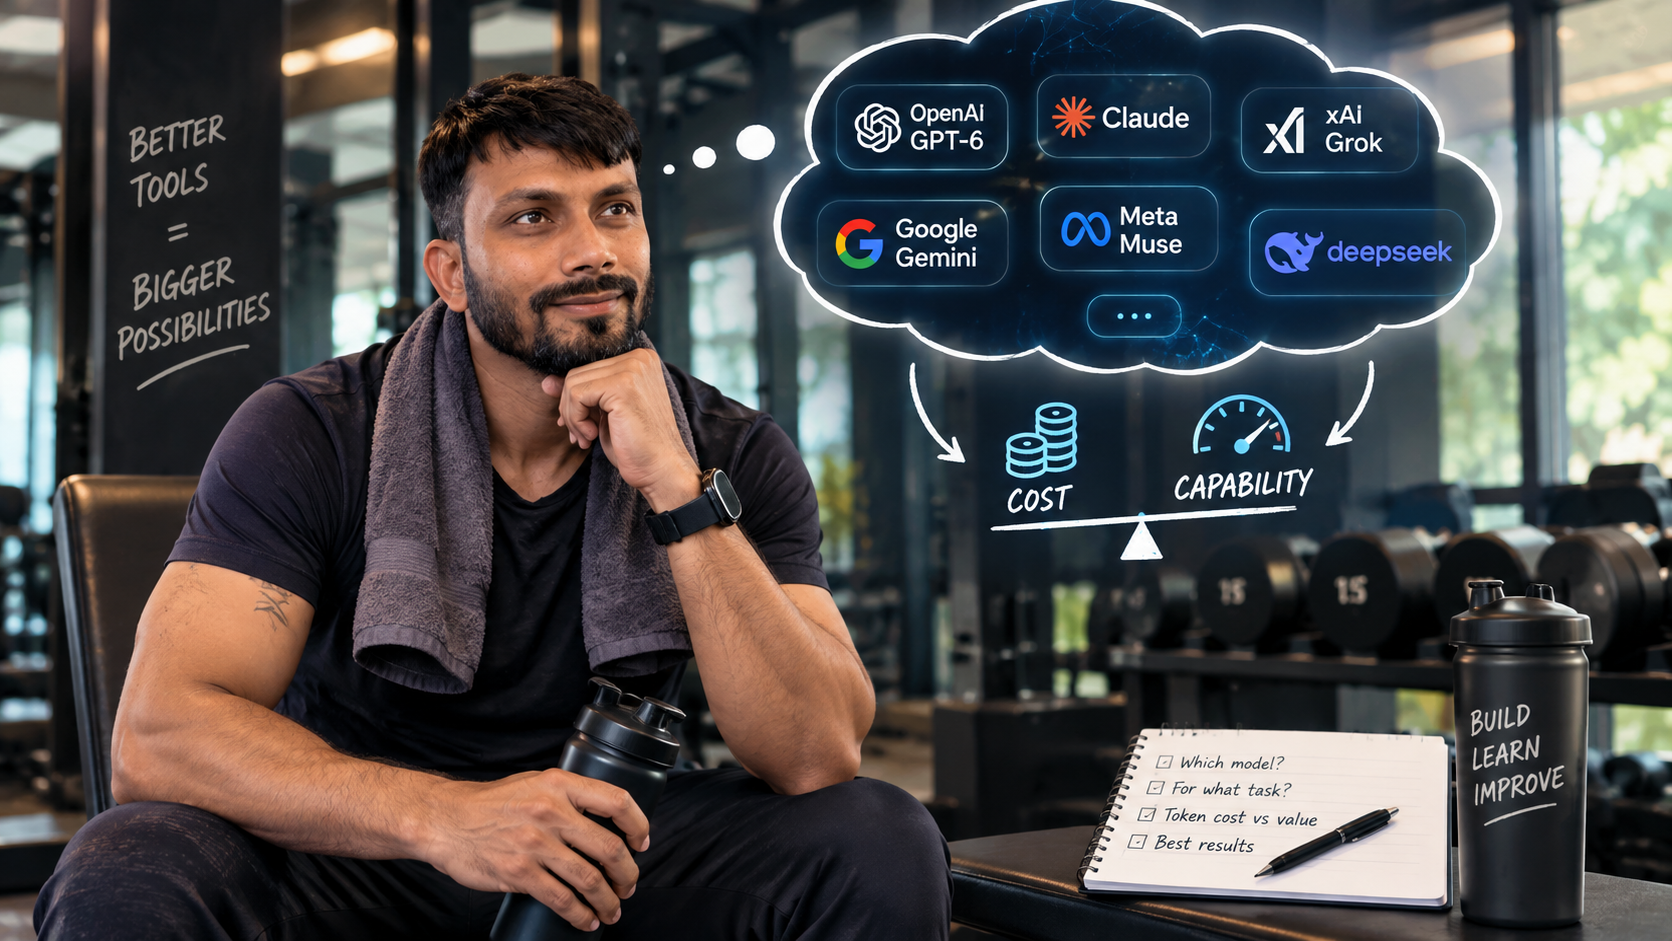
The AI race is moving faster than our ability to adapt. Perhaps it is time for developers to stop competing on which model they use and start competing on how effectively they use them.
I have been following AI coding models and developer tools for several years now. Over time, I have experimented with different models, compared their capabilities, and used AI more extensively in actual development work.
One thing has become increasingly clear: the biggest challenge for developers is no longer access to a capable model. It is deciding which model to use, when to use it, and whether the cost is justified by the result.
Look at what is happening across the industry.
OpenAI continues to evolve its models and Codex ecosystem. Anthropic is pushing Claude's reasoning and coding capabilities. xAI is competing with Grok. DeepSeek continues to put pressure on the economics of powerful models. Google is expanding Gemini and its agentic development ecosystem, while Meta is making another serious push with Muse Wonder.
Then there is a growing layer of tools around these models: Claude Code, Codex, Muse Code, Google Antigravity and AWS Kiro, among others.
Every company is trying to convince us that its latest release can do more, reason better, write better code or operate more independently.
And every release creates another question for developers: Am I falling behind if I do not start using this immediately?
The fear of falling behind is becoming a problem of its own
Think about how software development worked for much of the period from the mid-1990s through the early 2020s.
We worked with relatively stable technology stacks. Frameworks evolved, platforms improved, and new architectures emerged, but teams generally had enough time to learn a technology, establish engineering practices, build products and operate them before the next major shift demanded attention.
That stability gave us room to develop expertise.
The AI era feels different.
New models arrive at a breathtaking pace. Benchmarks are published, leaderboards change, demonstrations become viral, and developers immediately begin evaluating whether their existing tools are still good enough.
We can spend more time comparing models than using them to solve actual problems.
There is also a hidden cost. Switching models means revisiting prompts, evaluating behaviour, adjusting agent configurations, checking integrations and sometimes rethinking the development workflow itself.
The irony is that AI is supposed to make us more productive. Yet the continuous pressure to keep up can consume the very time we hoped to save.
I am not suggesting that developers should stop experimenting. Quite the opposite. We need to experiment more intelligently.
The goal should not be to use every new model. The goal should be to understand which models deliver the best results for the work in front of us.
Muse Wonder is an interesting example of where the market stands
I am currently exploring Meta's Muse ecosystem, particularly the newly announced Muse Wonder models.
Meta introduced Muse Wonder and Muse Wonder Full on 12 October 2026, positioning them around agentic work, coding, memory and longer-running tasks. The models are designed to maintain context, recover from errors and continue working towards a goal rather than simply responding to a single prompt.
That direction is interesting because it moves the conversation beyond generating code snippets. The more important question is whether an agent can understand a requirement, work across a codebase, execute tests, recover from failures and produce a working result with less intervention.
But after looking at the available results, my initial view is measured: Muse Wonder is a credible competitor, but I would not call it an across-the-board breakthrough simply because it crosses certain benchmark thresholds.
Meta's own Muse Wonder model card and benchmark report show a mixed picture.
For example:
Long-horizon coding: Muse Wonder Full scores 79.0 on DeepSWE 1.1, compared with 74.1 for GPT-6 Astra and 74.2 for Claude Opus 5.5 in Meta's reported comparison.
Extended software engineering: It scores 57.5 on SWE-Marathon, compared with 46.3 for Claude Opus 5.5 and 42.5 for GPT-6 Astra. The reported configurations are not a fully controlled, identical-tool comparison, so these figures should be interpreted cautiously.
General professional work: Muse Wonder Full scores 59.1 on Meta's Personal Superintelligence Index. That is ahead of GPT-6 Astra at 54.5 and Claude Opus 5.5 at 55.2 in this particular comparison. However, this is a Meta-defined composite index.
Other tasks: It scores 57.1 on Terminal-Bench 4.0-AA, below Claude Opus 5.5 at 59.6. On HealthBench Pro, it scores 62.3, compared with 65.3 for GPT-6 Astra and 65.6 for Claude Opus 5.5. On ProgramBench, it records 59.0 versus 70.5 for Opus.
These figures are taken from Meta's published model card; they are not a universal, independently reproduced ranking of every model in every environment.
My takeaway is simple: Muse Wonder Full appears genuinely competitive, particularly on some longer-running agentic coding tasks. However, the results do not establish that it is the best choice for every development workload.
And that is exactly why I think our evaluation criteria need to change.
We should neither dismiss a model because it loses one benchmark nor declare a winner because it tops another.
A model that performs exceptionally well on a demanding repository-level engineering task may not be the most economical option for writing unit tests, transforming JSON, generating boilerplate or processing thousands of routine requests.
Capability matters, but capability without context is an incomplete purchasing decision.
Token prices are only half the story
Let's look at some actual API pricing.
The following examples use published USD prices per million input and output tokens, checked on 13 October 2026. Prices depend on model versions, service tiers, context length, caching and other conditions. These are API prices, not equivalent monthly coding-tool subscriptions.
Model
Input / output per 1M tokens
Where I would evaluate it first
DeepSeek V4.1 Flash
$0.15 / $0.60 off-peak
High-volume, straightforward tasks; initial cost-efficient candidate
OpenAI GPT-6 Luna
$0.10 / $0.50
Low-cost routing, extraction and simpler tasks
xAI Grok 4.7
$2 / $6
Coding, tool calling and reasoning-heavy workflows
OpenAI GPT-6.1 Sol
$2 / $10
General-purpose development and tasks needing more capability than a lightweight model
Anthropic Claude Sonnet 5.5
$2 / $10
Everyday coding, refactoring and general engineering assistance
Google Gemini 4 Argon
$2 / $10 introductory pricing
Complex coding and agentic workflows; launch pricing is scheduled to increase
Meta Muse Wonder
$4 / $20
Agentic coding, long-running tasks and multi-step workflows
Anthropic Claude Opus 5.5
$4 / $20
Difficult engineering tasks and sustained agentic work
OpenAI GPT-6 Astra
$10 / $50 for context under 200K tokens
High-capability reasoning and demanding tasks where its additional capability justifies the cost
Sources: OpenAI API pricing, Anthropic model pricing, xAI model pricing, Meta Model API pricing, Google Gemini pricing and launch information, and the published DeepSeek V4 pricing guide. DeepSeek's published rates vary by peak and off-peak periods, so its current official rate card should be checked before production budgeting.
For Gemini 4 Argon, the announced introductory API rate is $2 per million input tokens and $10 per million output tokens through 30 November 2026, with rates scheduled to double afterwards. See the launch coverage.
For Meta, the $4/$20 rate applies to Muse Wonder. Muse Wonder Full is currently offered through Muse Code subscriptions rather than a separately published per-token API rate; the two should not be treated as interchangeable pricing options.
One useful way to make the comparison tangible is to imagine a workload consuming one million input tokens and generating one million output tokens.
Under the rates above, that would cost approximately:
DeepSeek V4.1 Flash: $0.75 off-peak
Grok 4.7: $8
Claude Sonnet 5.5: $12
Muse Wonder: $24
Claude Opus 5.5: $24
GPT-6 Astra: $60, using the standard short-context rate
This is an illustrative calculation, not a prediction of the cost of a particular coding session. Real workloads rarely consume equal amounts of input and output, and caching, reasoning tokens, retries and tool calls affect the final bill.
Nevertheless, it illustrates the economic spread between available options.
The most expensive model is not automatically the most economical choice for every task.
What if a cheaper model uses more tokens?
This is the question I find more interesting than the raw price comparison.
Suppose Model A costs $2 per million output tokens, while Model B costs $10. At first glance, Model A appears to be the obvious choice.
But suppose Model A repeatedly misunderstands the requirement, generates unnecessary code, consumes more context and needs three additional attempts. Model B solves the task correctly on its first attempt.
The cheaper model might end up costing more.
The reverse is equally possible: an advanced model might solve the task perfectly, but its extra reasoning and capability provide no meaningful benefit for something as straightforward as formatting a response or mapping two data structures.
That is why I would not compare models solely on tokens consumed or their advertised intelligence.
I would measure cost per successful task.
The calculation should include the actual token bill, the number of retries, latency, tool execution and the amount of human review needed to reach a correct result. For development tasks, correctness should include passing the relevant tests and meeting the requirements, not merely generating code that looks plausible.
Consider three hypothetical outcomes:
Approach
Total AI cost
Outcome
Cost per successful task
Lightweight model, one attempt
$0.05
Fails verification
No successful result
Lightweight model, retries
$0.15
Passes tests
$0.15
Advanced model, one attempt
$0.20
Passes tests
$0.20
In this example, the lightweight model remains the economical choice even after retries. If the retries increase its cost to $0.30, the advanced model becomes cheaper per successful task.
Neither outcome is predetermined by the model's headline price.
This is the level at which we should be comparing models in real projects.
I would not select one model for everything
My preferred approach is to create a practical model-selection strategy.
For simple, repetitive, high-volume work, I would start with a cost-efficient model such as DeepSeek V4.1 Flash or GPT-6 Luna and verify that it meets the quality threshold.
For everyday coding, maintenance, refactoring and implementation tasks, I would compare Claude Sonnet, GPT-6.1 Sol and Grok 4.7 against the actual codebase and engineering requirements.
For complex repository changes, difficult reasoning, architectural decisions and longer-running autonomous work, I would evaluate Claude Opus, Muse Wonder Full and GPT-6 Astra. The additional cost may be worthwhile when failures are expensive or when the task genuinely benefits from stronger reasoning.
For browser-based or multi-step workflows, I would evaluate the agent environment as well as the underlying model. Google's Antigravity and AWS Kiro are development environments, not model families themselves. Their ability to plan work, use tools, run tests, navigate applications and recover from errors can matter just as much as the raw capability of the model they use.
These are starting points for evaluation, not a universal ranking. The right choice can change with the language, repository, context size, toolchain, reliability requirements and budget.
How I would put this into practice
Rather than continuously changing the default model whenever a new benchmark appears, I would maintain a small evaluation suite based on real engineering work.
Take a representative set of tasks: fixing a bug, implementing an API endpoint, writing tests, refactoring a service, tracing a failure across multiple layers and completing a change that touches several parts of a codebase.
Run the candidate models against the same requirements and verification criteria.
Record whether the solution works, how many retries are needed, how much human intervention is required, how long it takes and what the full model usage costs.
Then establish a simple policy:
Use the most economical model that reliably meets the quality threshold.
Escalate to a stronger model when the task is complex, the first attempt fails or the consequences of failure justify the extra cost.
Re-evaluate the default model when a challenger demonstrates a meaningful improvement on our own workloads—not merely because it tops a new leaderboard.
Keep the model layer replaceable so the application or development workflow is not unnecessarily tied to one provider.
This also creates a more useful engineering culture. Instead of debating which company has the smartest model, developers can demonstrate which configuration delivers the best results for a particular workload.
The race we should be running
I am still going to experiment with new models. I want to understand where Muse improves, where Claude remains stronger, where OpenAI offers better value, where Grok fits and where lower-cost models are already good enough.
But I no longer think the right objective is to stay on the newest model at all times.
The frontier will keep moving. Today’s leader will face tomorrow’s challenger, and a benchmark victory will eventually be overtaken by another release.
We cannot build a sustainable engineering practice around chasing every launch.
We can, however, build one around good evaluations, sensible model routing, measurable outcomes and the discipline to pay for capability only when we need it.
The next competitive advantage may not belong to developers with access to the most powerful model. It may belong to developers who know exactly when not to use it.
That is the race I think we should be running.
Have a similar workflow?
Discuss what a focused first project could involve. Tell us which article you read.